AlgoWay Blog
Guides, manuals and platform references.
Core
- All articles
- FAQ
- PineConnector alternative
- TradersPost alternative
- Automate TradingView alerts
- Automate Telegram signals
- AlgoWay CopyTrader
- cTrader Copier
- TrendSpider with AlgoWay
- How to Automate a TradingView Indicator with Dynamic SL/TP and 1% Risk on MT5
JSON & Alerts
- JSON schema
- Manual alerts
- TradingView without paid subscription
- AlgoWay Strategy Integration in Pine Script
- Python Trading Bot Webhook Integration
- TRALADAL - TradingView Alert Adapter
- TradingView Order Action Alert
- How to use Clone Mode
MT5 / Expert Advisors
Errors
Integrations
- MetaTrader 5
- Tradovate
- TradeLocker
- cTrader
- Match-Trader
- DXtrade
- Capital.Com
- Binance
- Bybit
- MEXC
- OKX
- Bitget
- Hyperliquid
- BingX
- Alpaca
- Interactive Brokers
- Gate.io
- Coinbase
- TooBit
- WEEX
- KuCoin
- Kraken
- ProjectX
- Rithmic
Other Publications
- MT5 EA Webhook JSON Reference
- OANDA MT5 with AlgoWay
- Buy Webhook via Buy Me a Coffee
- AlgoWay vs PineConnector
- Compare AlgoWay with other trading automation tools
- AlgoWay Red News Filter
- Why Paid Trading Indicators Avoid Verifiable Backtests
- How Trade Automation Tools Mislead You
- utomating a Prop-Firm Eval End to End:
- ATP Premium Indicator Testing Bot
- Why TradingView Backtests Win but Live Trades Lose
- Best Prop Firms for Trading Automation and Telegram Signal Copy in 2026
- Four AIs, One Trader, and the Strange Case of TradingView to Alpaca
- TradingView Automation
AlgoWay Strategy Lab
Trading Model Validation: Why Random Splits Mislead
Imagine training a trading model on September observations, asking it to predict an August outcome, and calling the answer out of sample. The August row may be absent from training. September is still in its future.
For a model intended to predict future market observations, evaluate in the same direction that it will operate: learn from earlier information, then predict later observations. Randomly distributing time-ordered rows can test a different problem. Before a model's decisions enter an automated trading workflow, its evaluation should respect what was available at each decision time.
This sits upstream of execution. If you later use an AlgoWay alert-to-order workflow, successful order delivery does not validate the model that chose the trade. Keep the prediction experiment and the execution check as separate records.
What shuffling changes
Suppose a research dataset contains January through December, with one row per completed trading bar. A random 80/20 split can put November in training and March in testing. It asks whether a model fitted with information scattered through the year can predict withheld rows. It does not reproduce fitting at the end of February and facing an unseen March.
Adjacent observations can also share much of their recent history. A random seed makes the split reproducible; it does not put time back in order. This is a reason to question the experiment, not proof that every shuffled score must improve.
Scikit-learn's lagged-feature forecasting example demonstrates overly optimistic error estimates from a shuffled split compared with time-based evaluation. That example forecasts demand, not trading returns. It supports the evaluation principle, not a claim about the profitability of a trading model.
Draw the evaluation calendar first
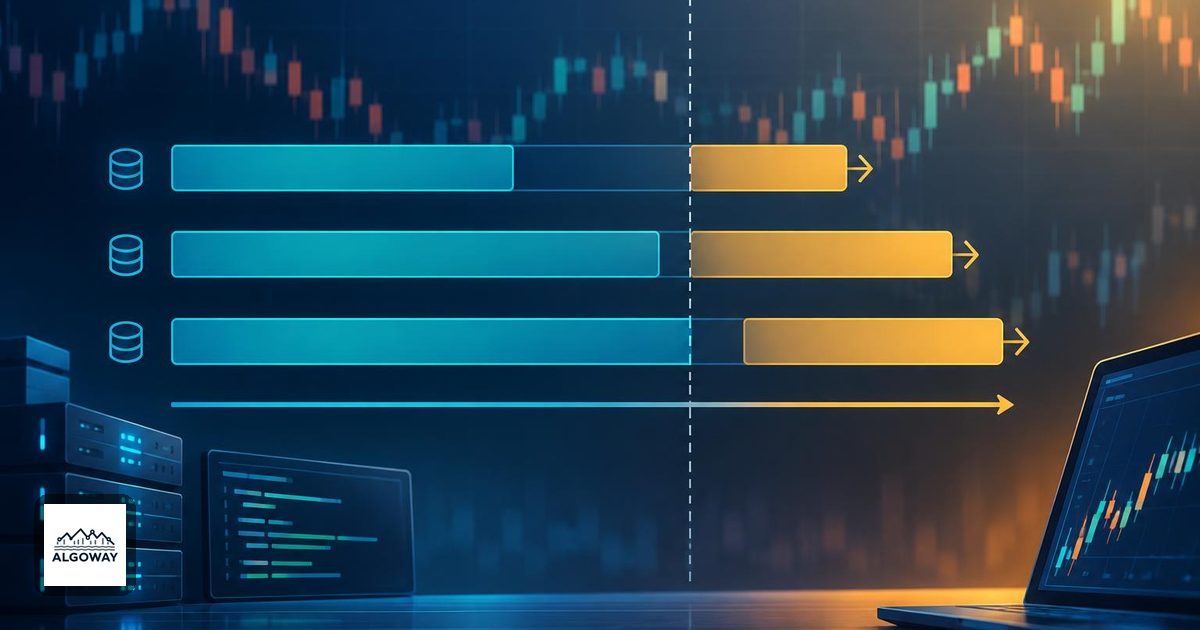
Here is an illustrative expanding-window design. It specifies when fitting happens, without inventing any scores.
| Stage | Fit using | Evaluate on | Purpose |
|---|---|---|---|
| Validation fold 1 | January to March | April | First later-period check |
| Validation fold 2 | January to April | May | Repeat after scheduled refit |
| Validation fold 3 | January to May | June | Compare stability across periods |
| Final holdout | Eligible January to June observations | July | Evaluate the frozen design once |
Training rows must have their outcomes available by the fitting cutoff. The calendar is not permission to use an unfinished target from the last training day. If you change features, thresholds or model settings after reviewing July, July has become development evidence. Reserve another untouched period for a later final check.
An expanding history retains older observations. A rolling window drops them, for example fitting only the latest three months before each evaluation month. Choose the schedule to match the intended operation. A model retrained monthly should not be evaluated as though it secretly retrained after every losing trade.
Use the splitter for the job it actually does
TimeSeriesSplit generates ordered training and test indices. Its default successive training sets expand; max_train_size can cap their size, test_size sets test sample count, and gap excludes samples immediately before the test block. Sort and inspect your timestamps first.
A gap is a count of samples, not automatically a duration. Ten rows may mean ten minutes in one dataset and several trading sessions in another. The documentation requires equally spaced samples for comparable fold durations. With irregular events or several instruments sharing timestamps, explicitly define time boundaries and keep the same decision time on the same side of each boundary.
A chronological split does not automatically resolve targets whose outcomes extend across that boundary. Inspect target availability separately. Nor does it repair a feature that reads tomorrow's close. The Freqtrade lookahead-analysis guide addresses a different check: whether strategy calculations depend on future data.
Keep learned preprocessing inside each training fold
Suppose your feature is a standardized return. If the mean and standard deviation come from January through July before the split, July has already influenced the input representation. Calculate learned transformation parameters from each training fold, then apply those same parameters to its later evaluation block.
The same separation applies to learned imputation, feature selection and dimensionality reduction. Scikit-learn's data-leakage guidance recommends fitting preprocessing only on training data and using pipelines to keep these operations together during cross-validation. A pipeline helps with learned transforms; it cannot make an incorrectly constructed future-looking column causal.
Save evidence that can survive a rerun
For each fold, retain the training cutoff, evaluation interval, target horizon, feature definitions, model settings, preprocessing fit window and retraining schedule. Save predictions with their decision timestamps before translating them into trades.
Then evaluate the trading policy separately: entry timing, exits, exposure and cost assumptions turn predictions into a hypothetical trading result. A good prediction score is not a net-profit statement. Look at each period as well as any aggregate, because one average can conceal a model that only worked in one stretch.
The useful question is not whether the test rows were hidden somewhere in a shuffled spreadsheet. It is whether the complete fitted decision process could have existed before those decisions had to be made.